Case studyWeb product · Node.js · Editorial design
CerebInk
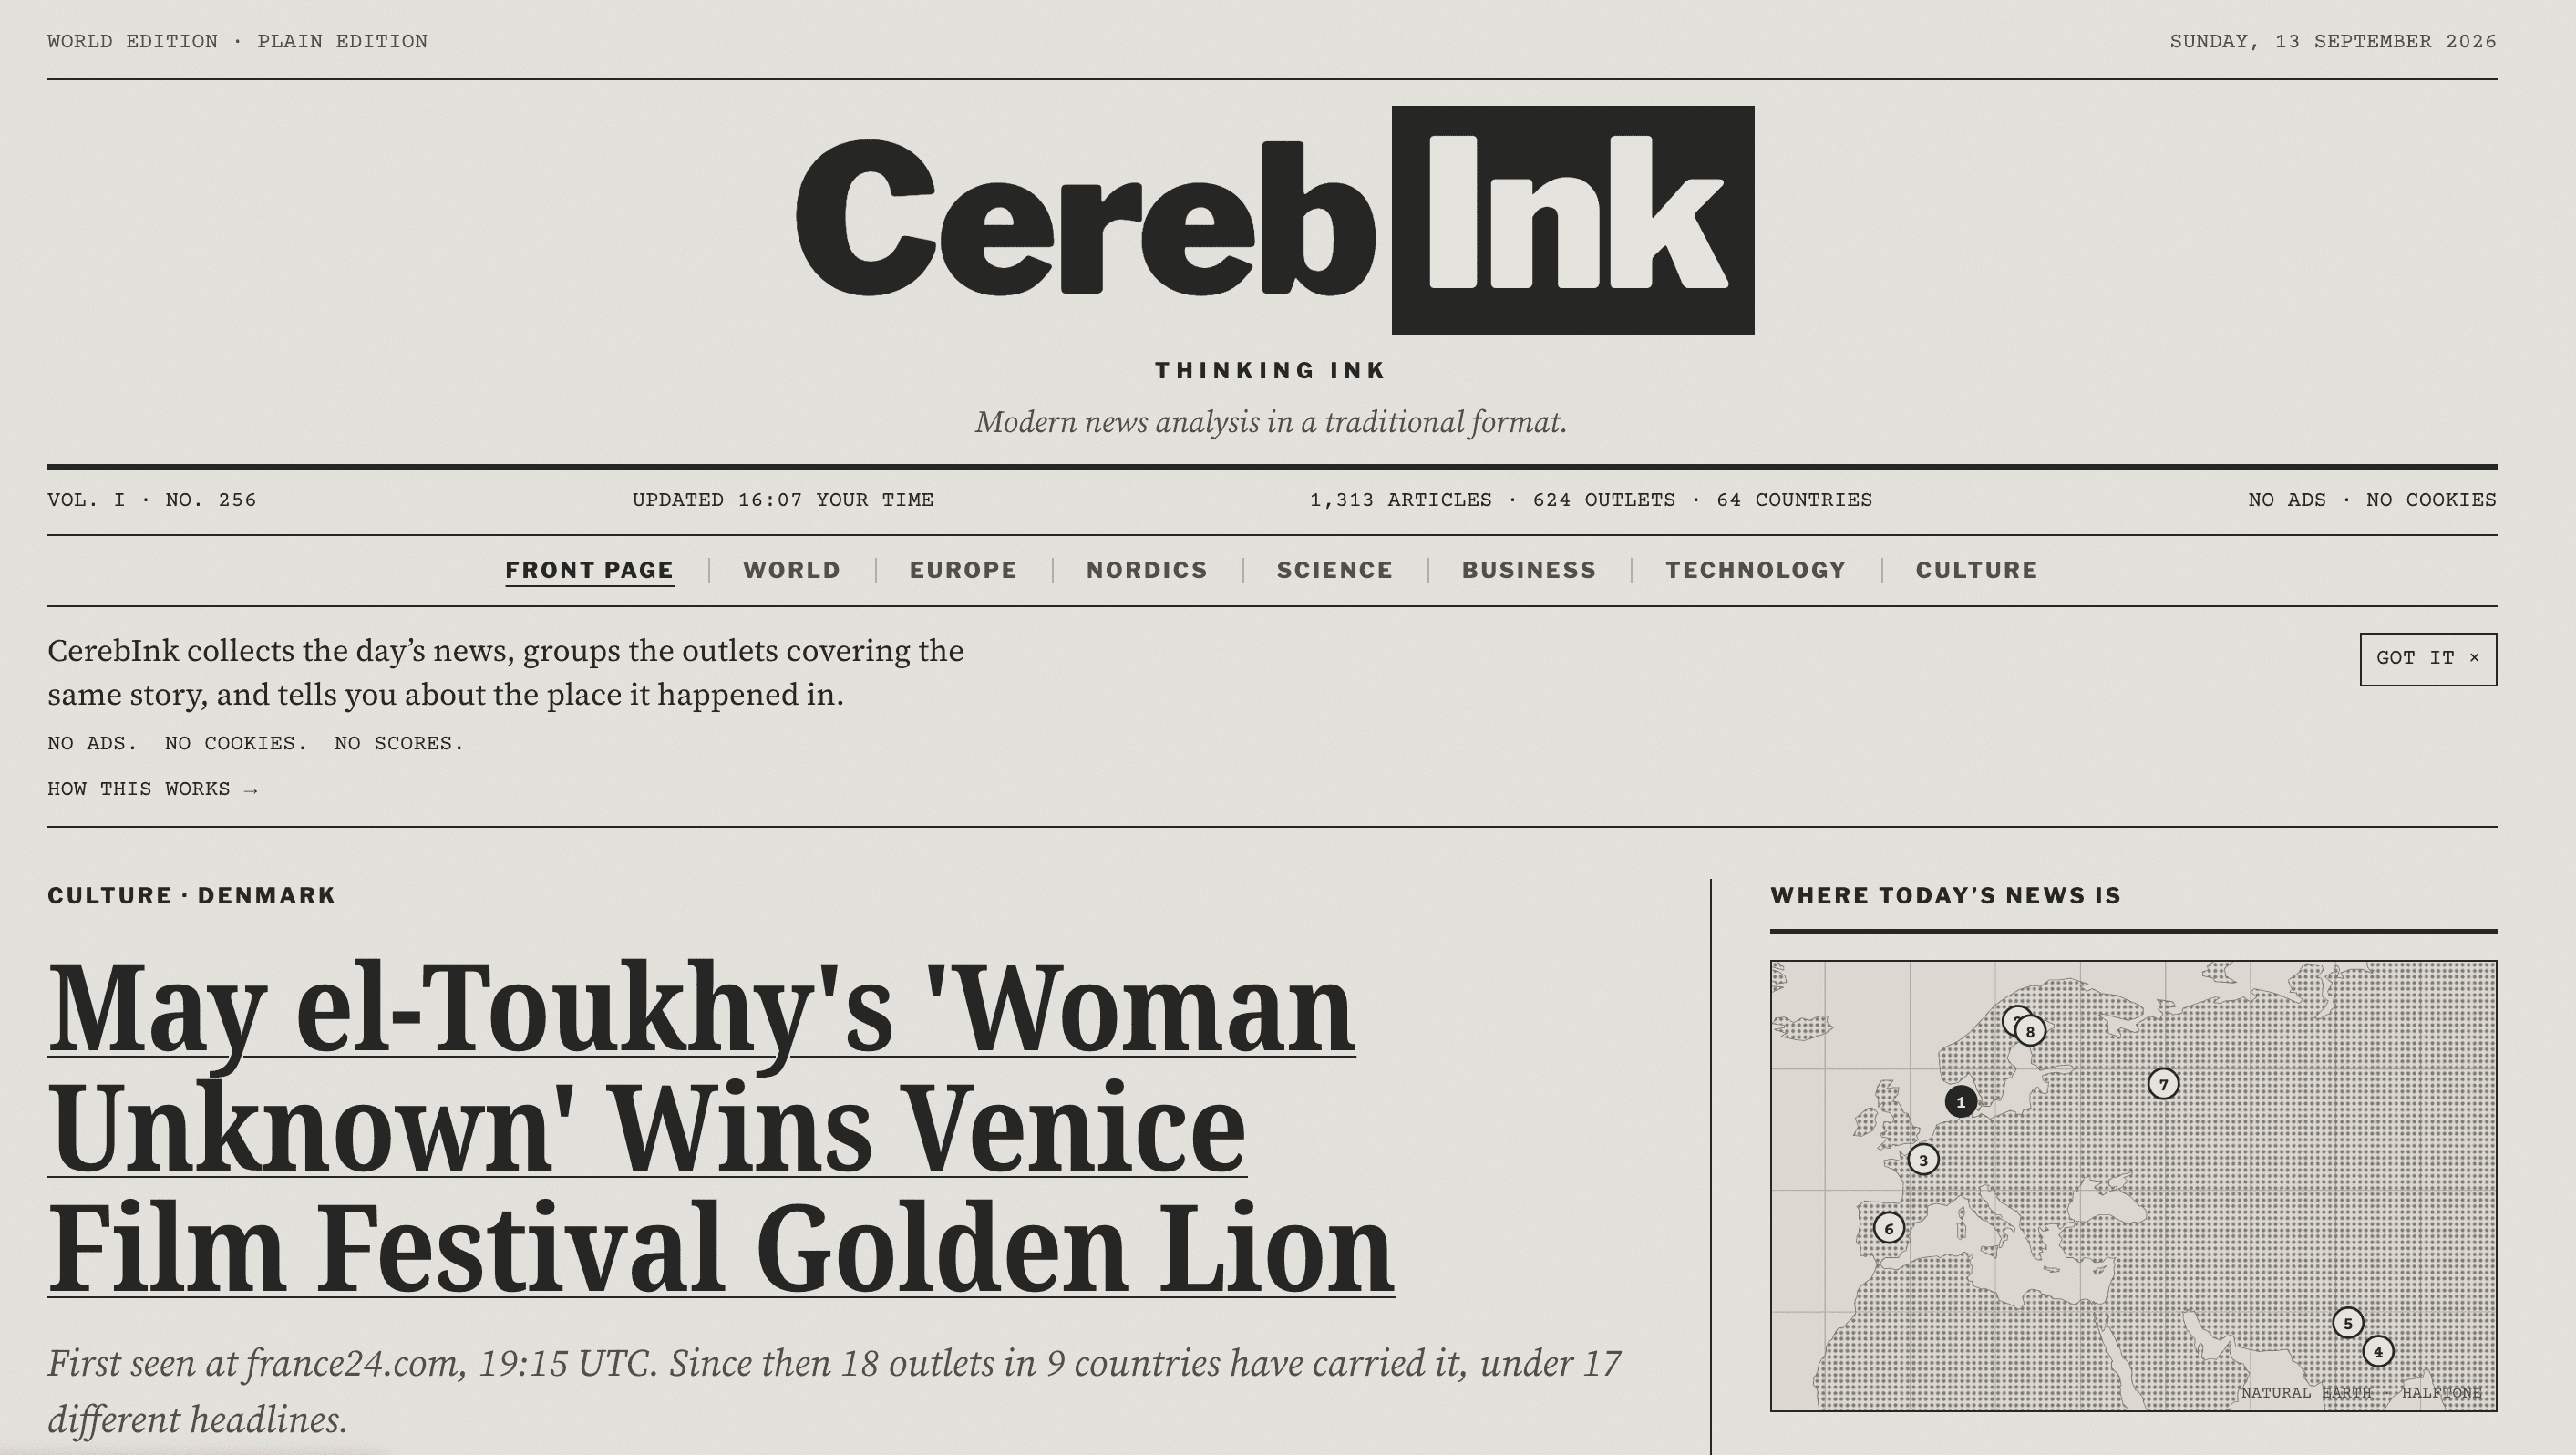
Reads 1,500 news articles a day, groups the ones telling the same story, and adds the ground beneath it: who lives there, the weather at press time, what happened there before. It publishes only what it is licensed to and cites every sentence it writes. Four editions a day, on the web, on a Kindle and on a reMarkable, set in 1980s newsprint. No ads, no cookies, no third-party trackers, and a daily comic strip, because it is my paper.
cerebink.com (opens in a new tab)
The itch
I read a lot of news and trusted less and less of how it reached me. Every outlet told the same story its own way, the important detail was three paragraphs down, and the page around it was built to keep me scrolling. I wanted a newspaper again: a finite edition, laid out once, with a job for everything on the page.
What CerebInk does
Every day it reads about 1,500 articles from the outlets it follows and works out which of them are the same story told twelve ways. Each story then gets its ground: who lives in the place it happened, what the weather was at press time, what has happened there before. Four editions a day come out of that, for the web, for a Kindle and for a reMarkable, because e-ink is where a paper is read slowly.
Only what it is licensed to
The rule that shaped everything: publish only what you are allowed to. Where a publisher allows it, the whole article appears. Where it does not, CerebInk writes its own account of the story from several outlets, and every sentence cites the outlet it came from. And often the honest answer is a headline and a link, and the page says so plainly.
The look
1980s newsprint, because on those pages everything had a job. Two typefaces, hairlines, a masthead, a plain edition that needs no JavaScript at all. No ads, no cookies, no third-party trackers. And a daily comic strip, because it is my paper.
How it is built
A Node.js pipeline collects, groups and writes the editions; the site itself is static and vanilla JavaScript with no dependencies, so it stays fast and cheap to run. Where CerebInk writes its own account, each sentence names the outlet it came from, and the whole account is thrown away if it borrows an outlet's phrasing or claims something the sources don't say.